What’s in the Back of My Mind
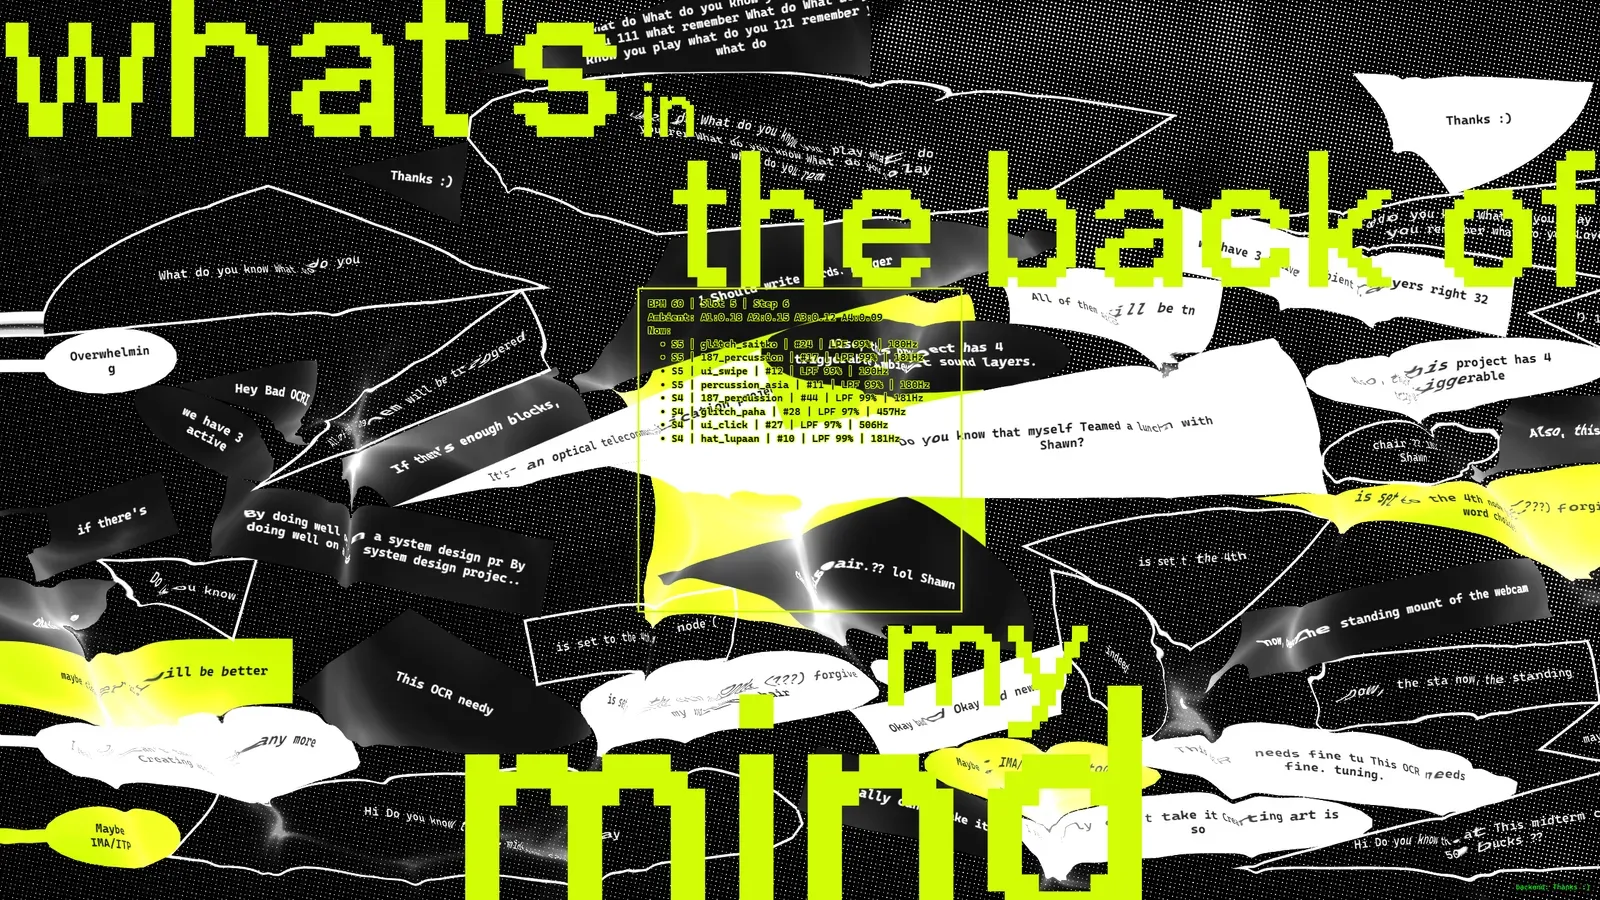
Title | All the Stuff in the Back of my Mind
Pitch | The words carry emotions, and those emotions become music. Or, in other words, you can “hear” my mind
Medium | Web
Concepts
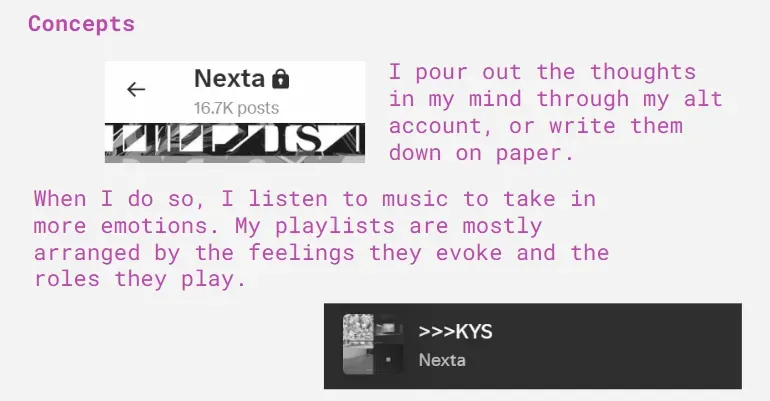
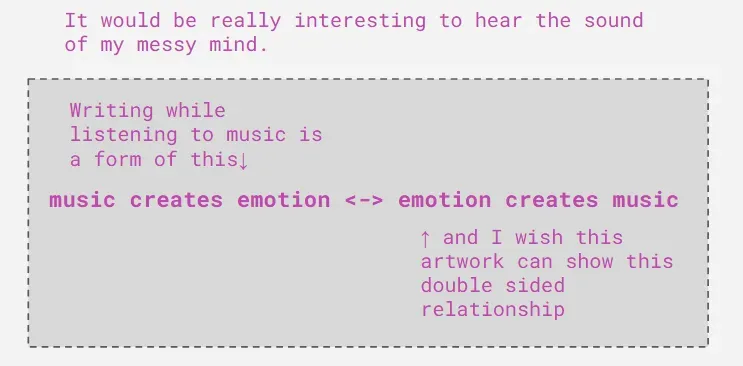
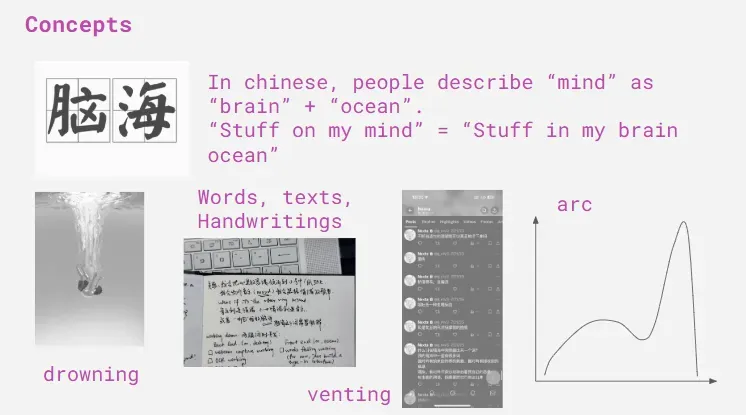
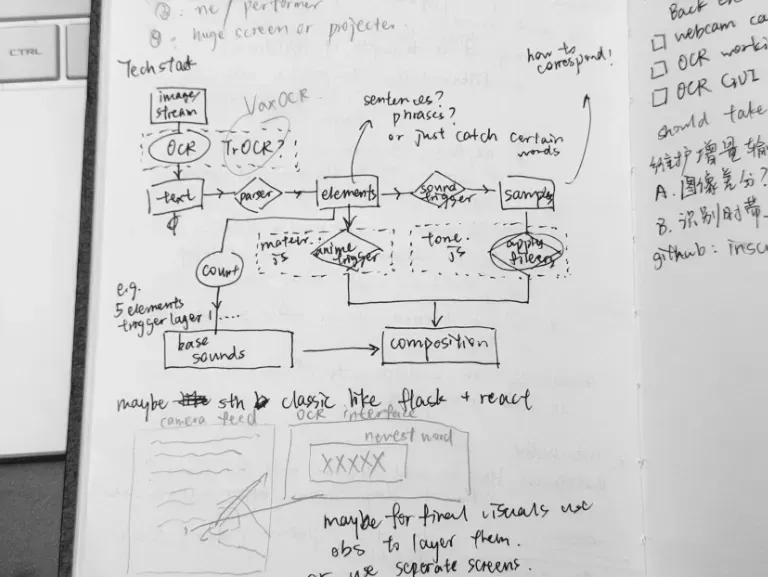
Visual Design
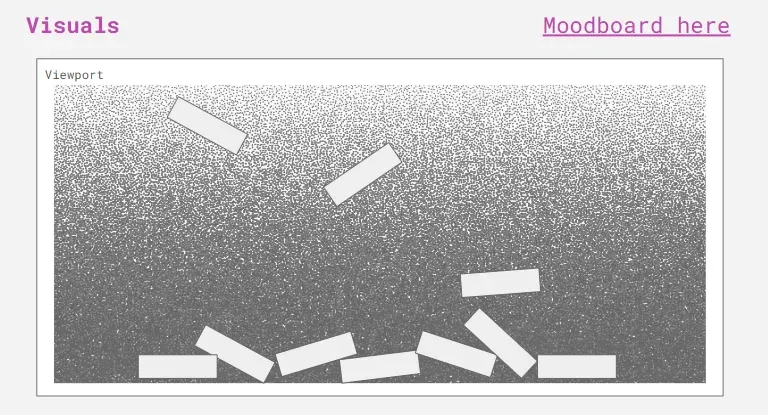
Matter.js
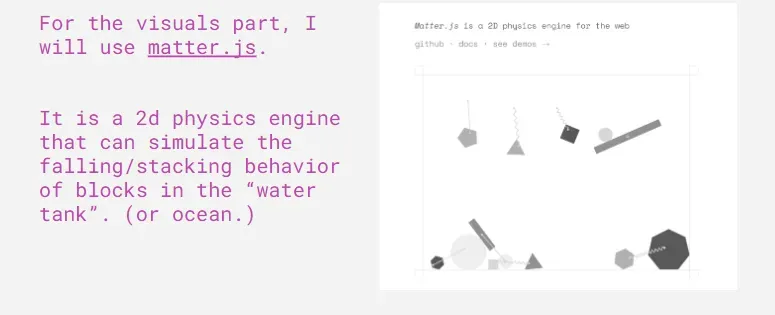
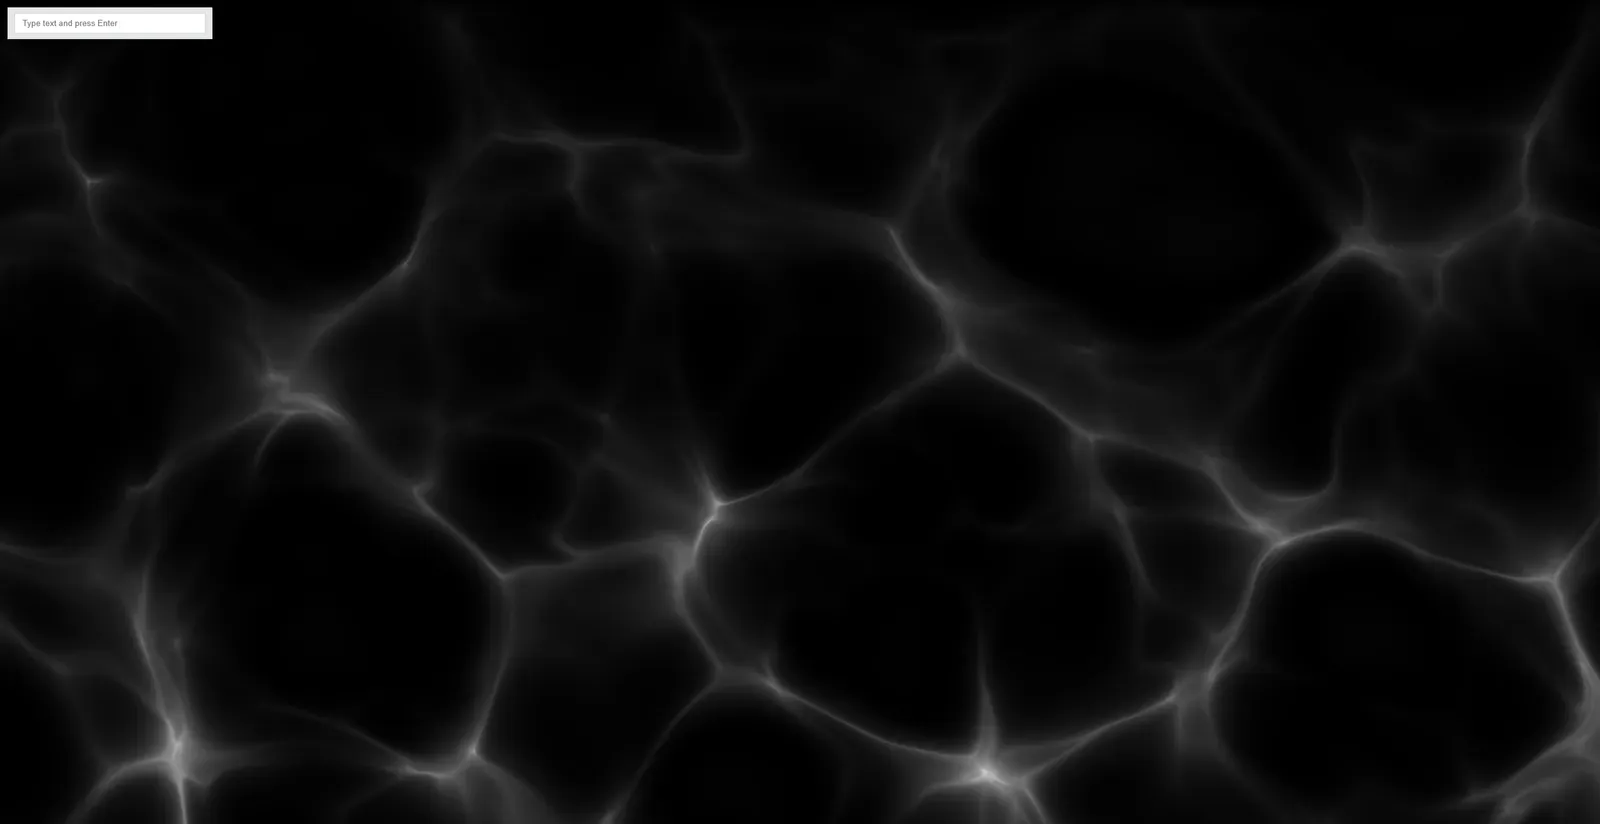
Water Shader
Thanks to this amazing code pen example, I was able to use WebGL to make this really sick water distortion effect: Lightweight Water Distortion Effect
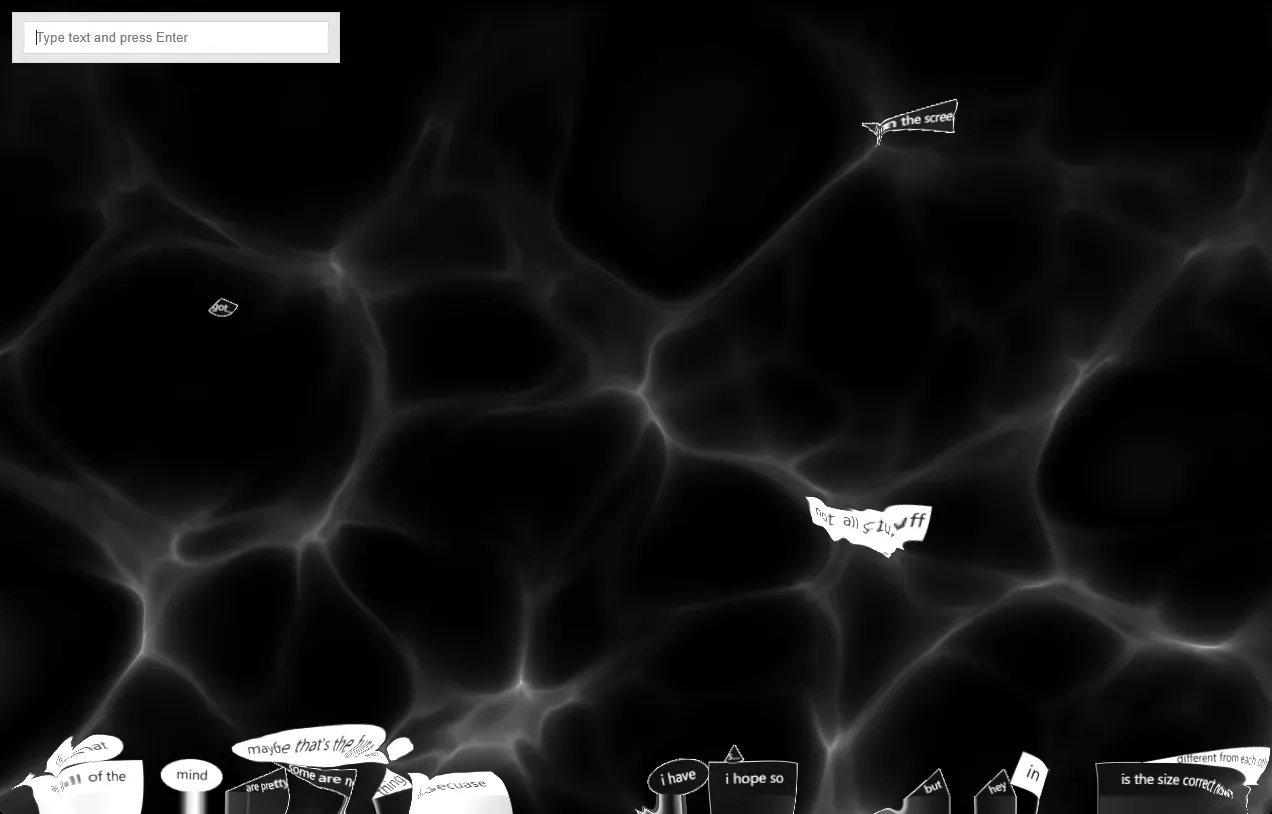
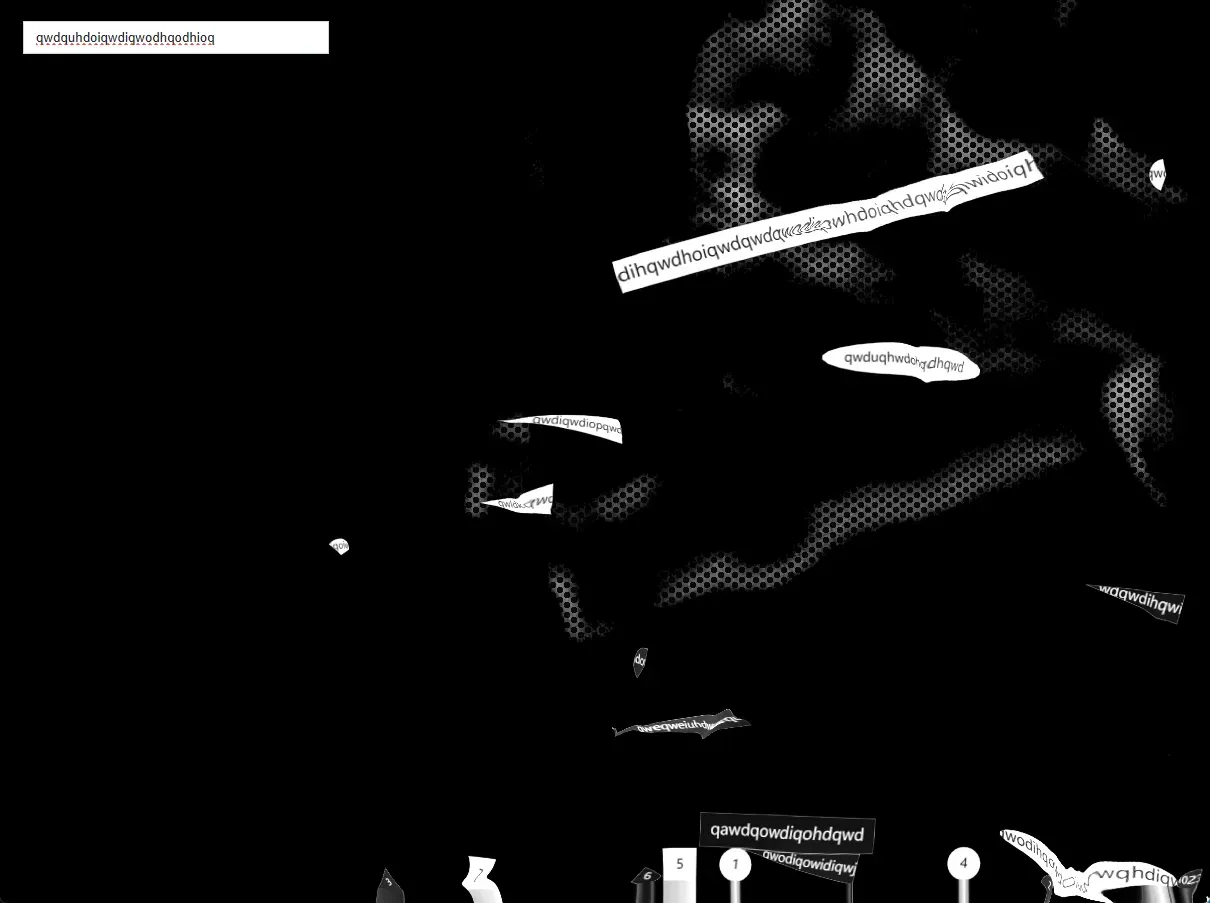
Mood board
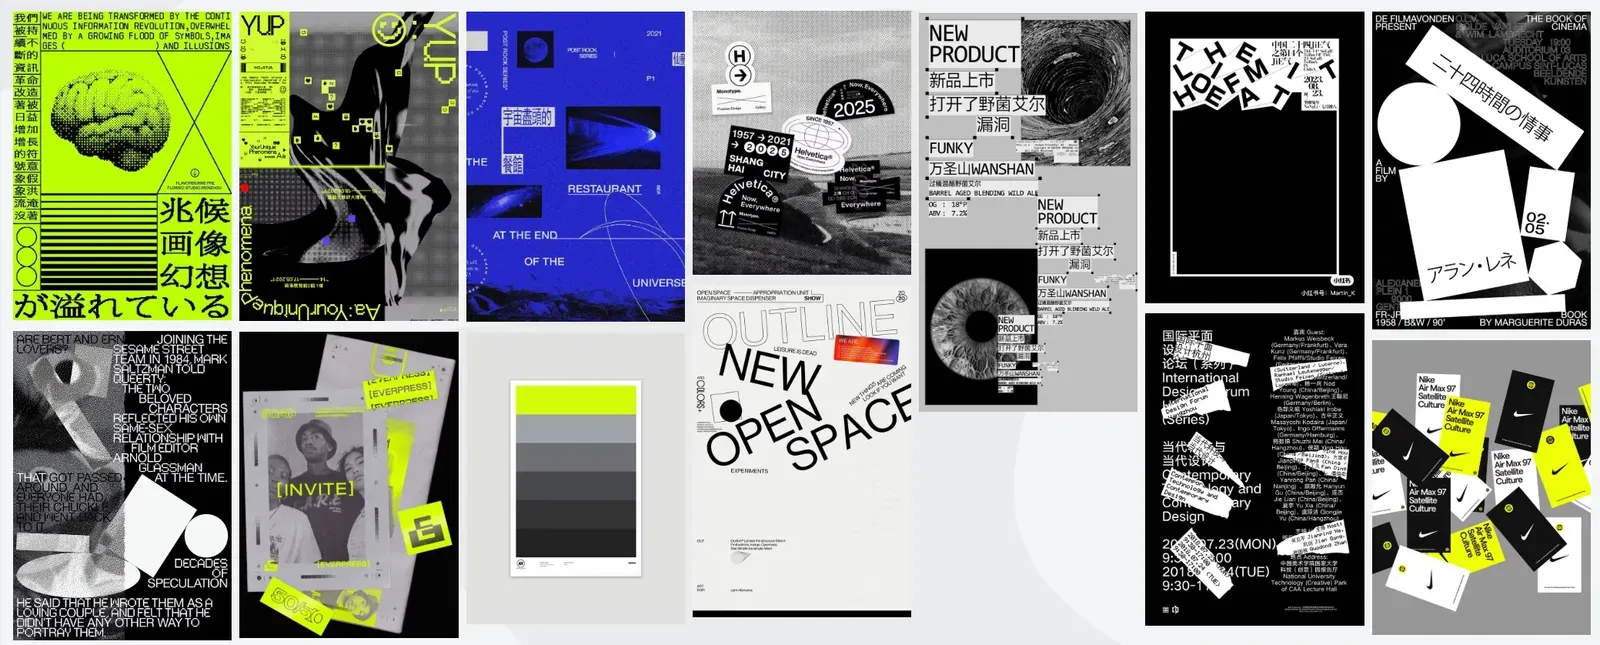
Layout Designs
背景视频:我拍摄的Luna在海边,脚边卷起浪的一段视频
加入一些重点色
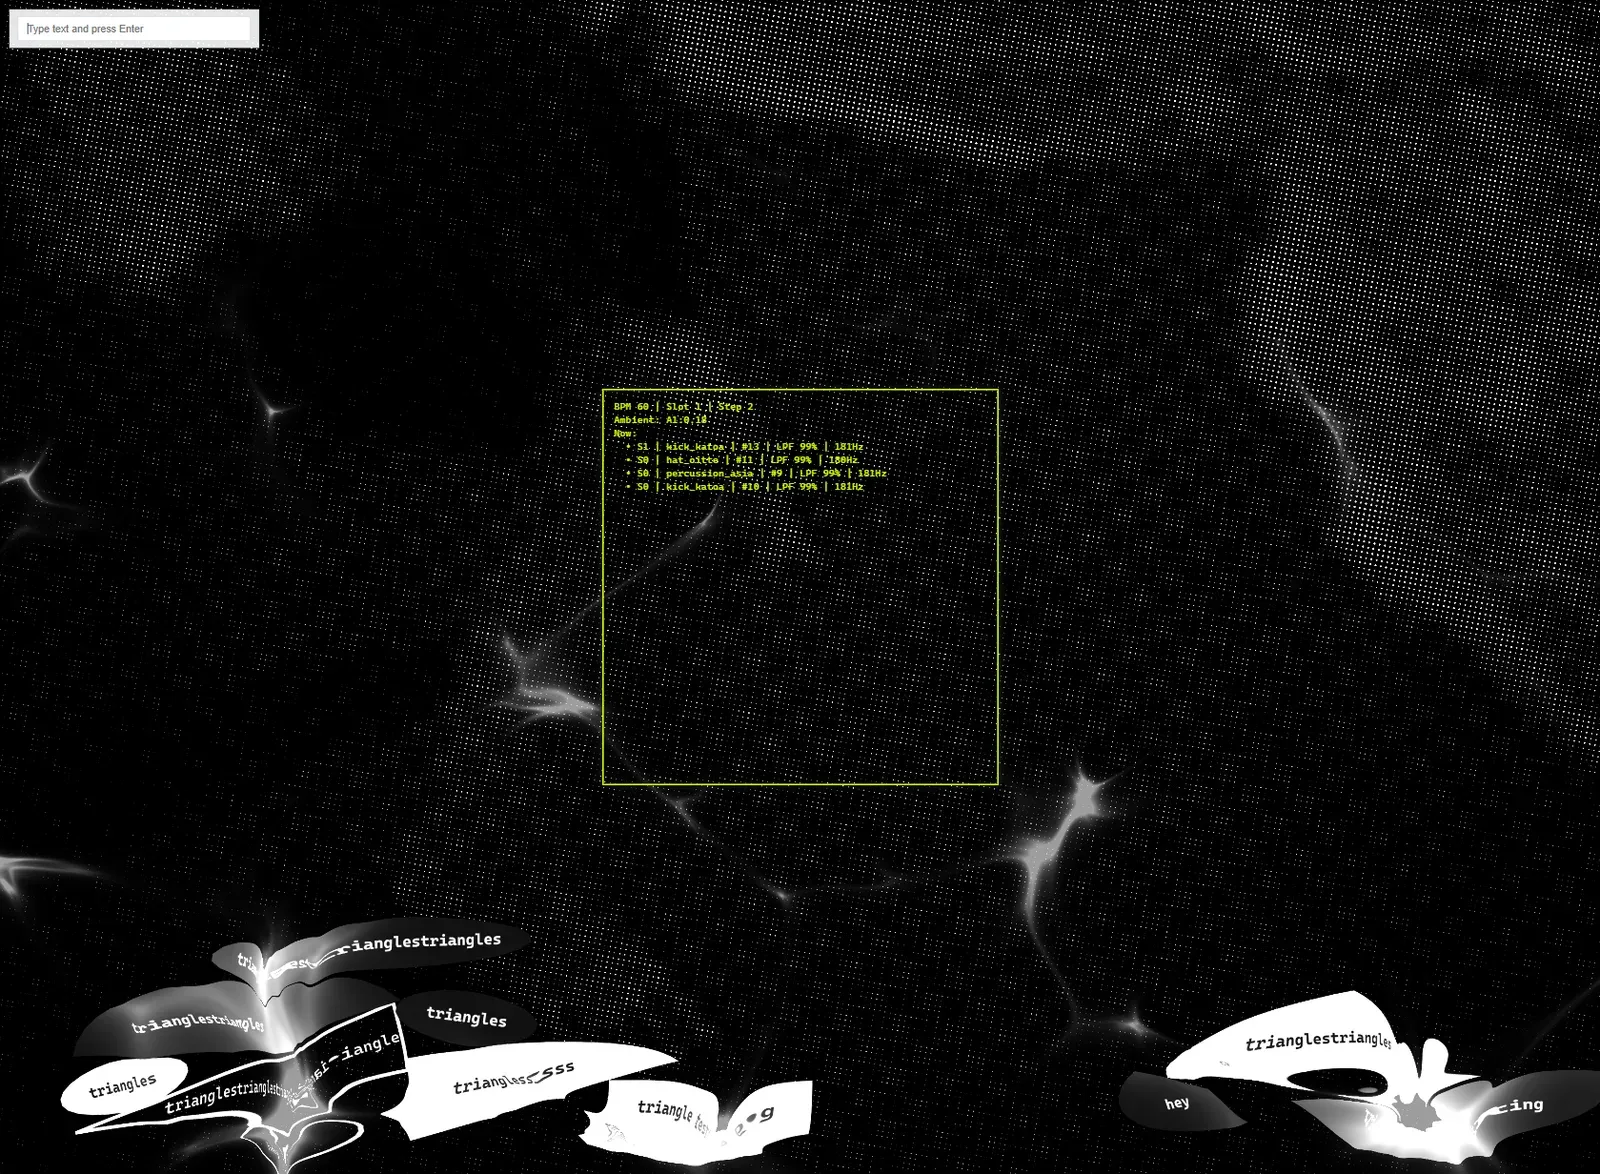
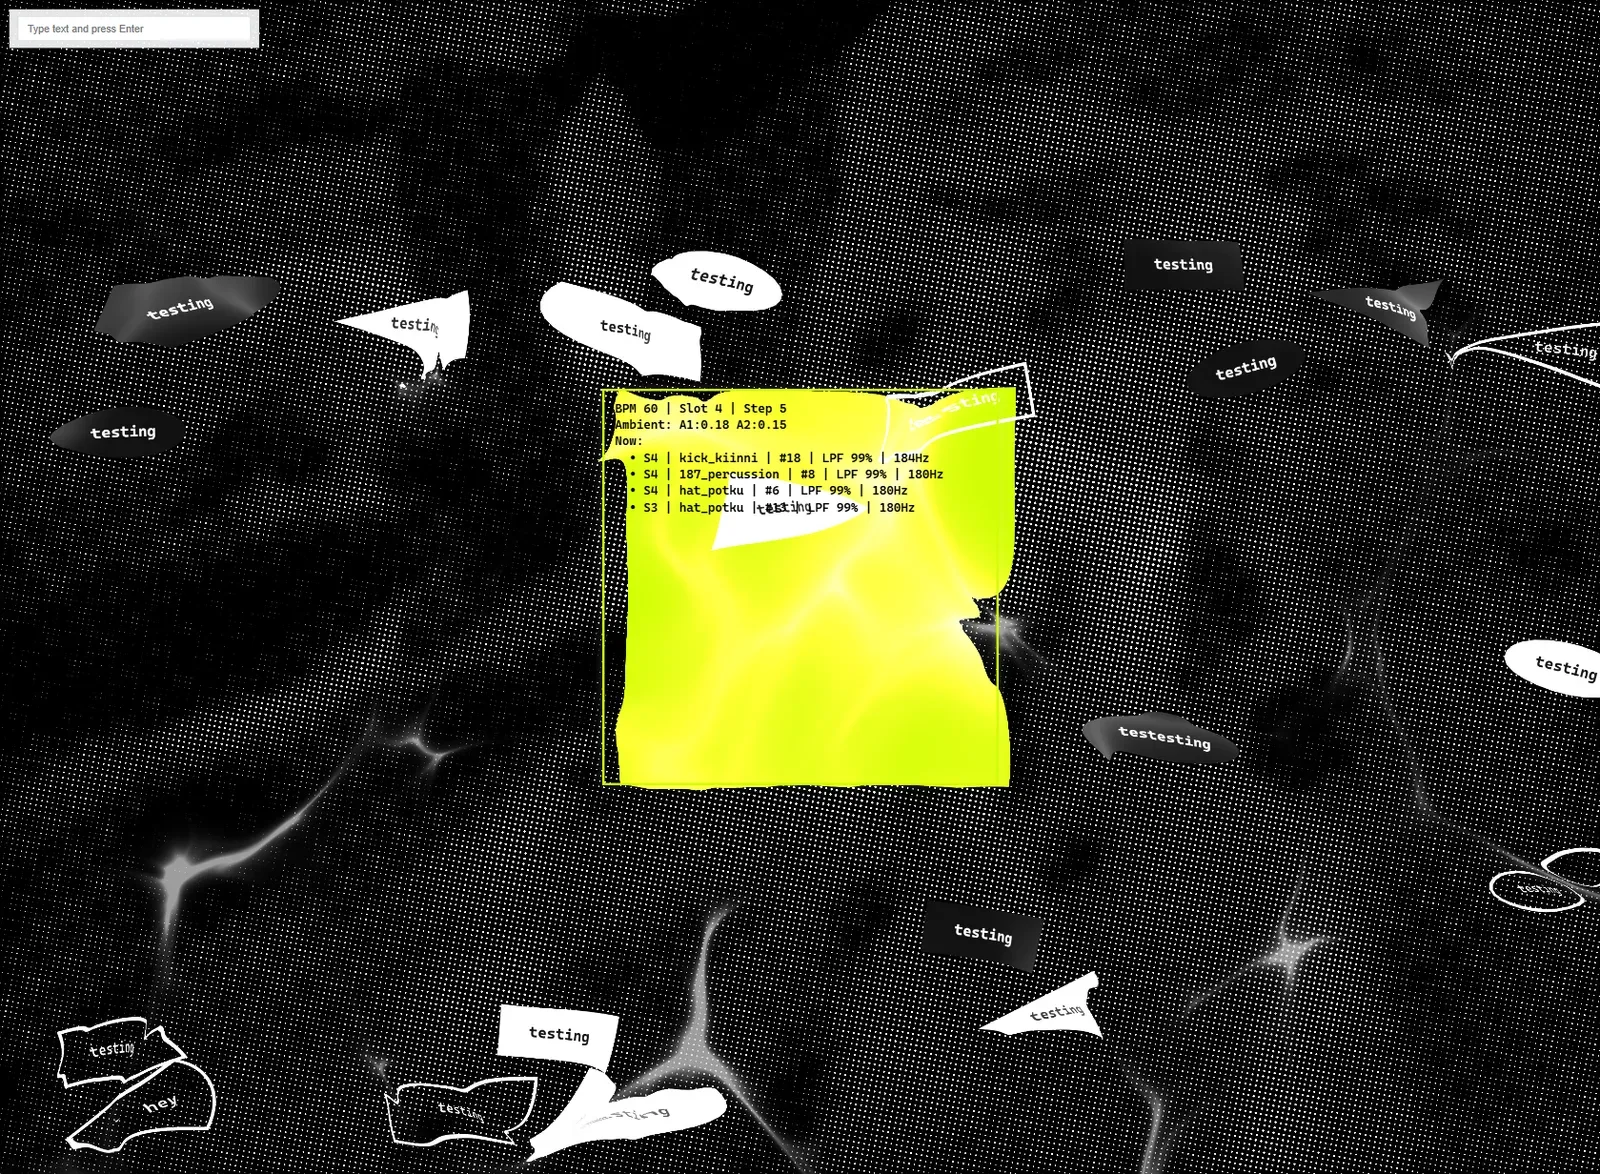
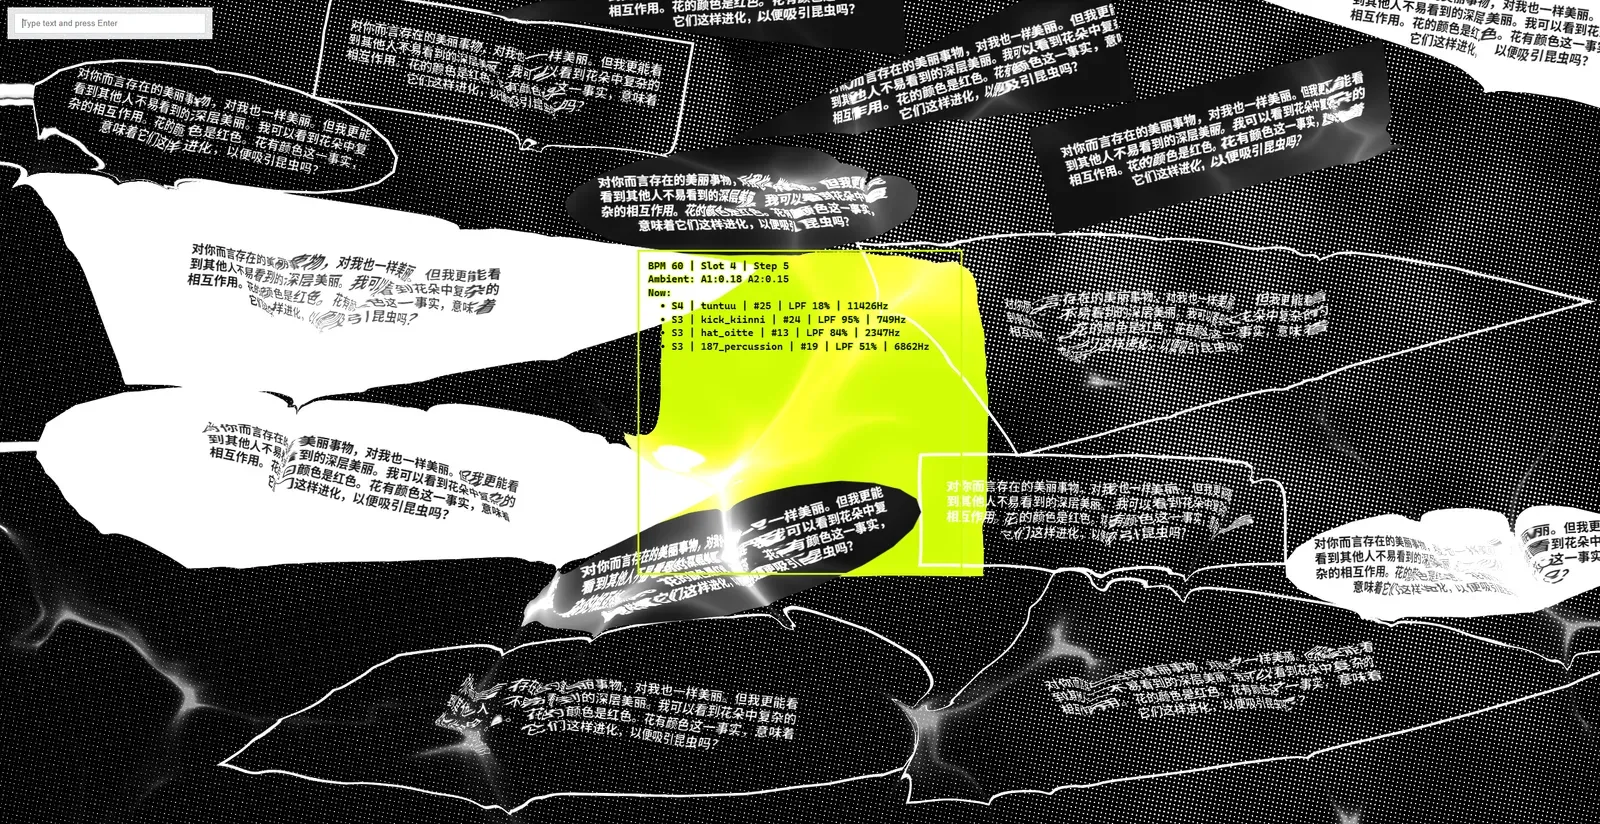
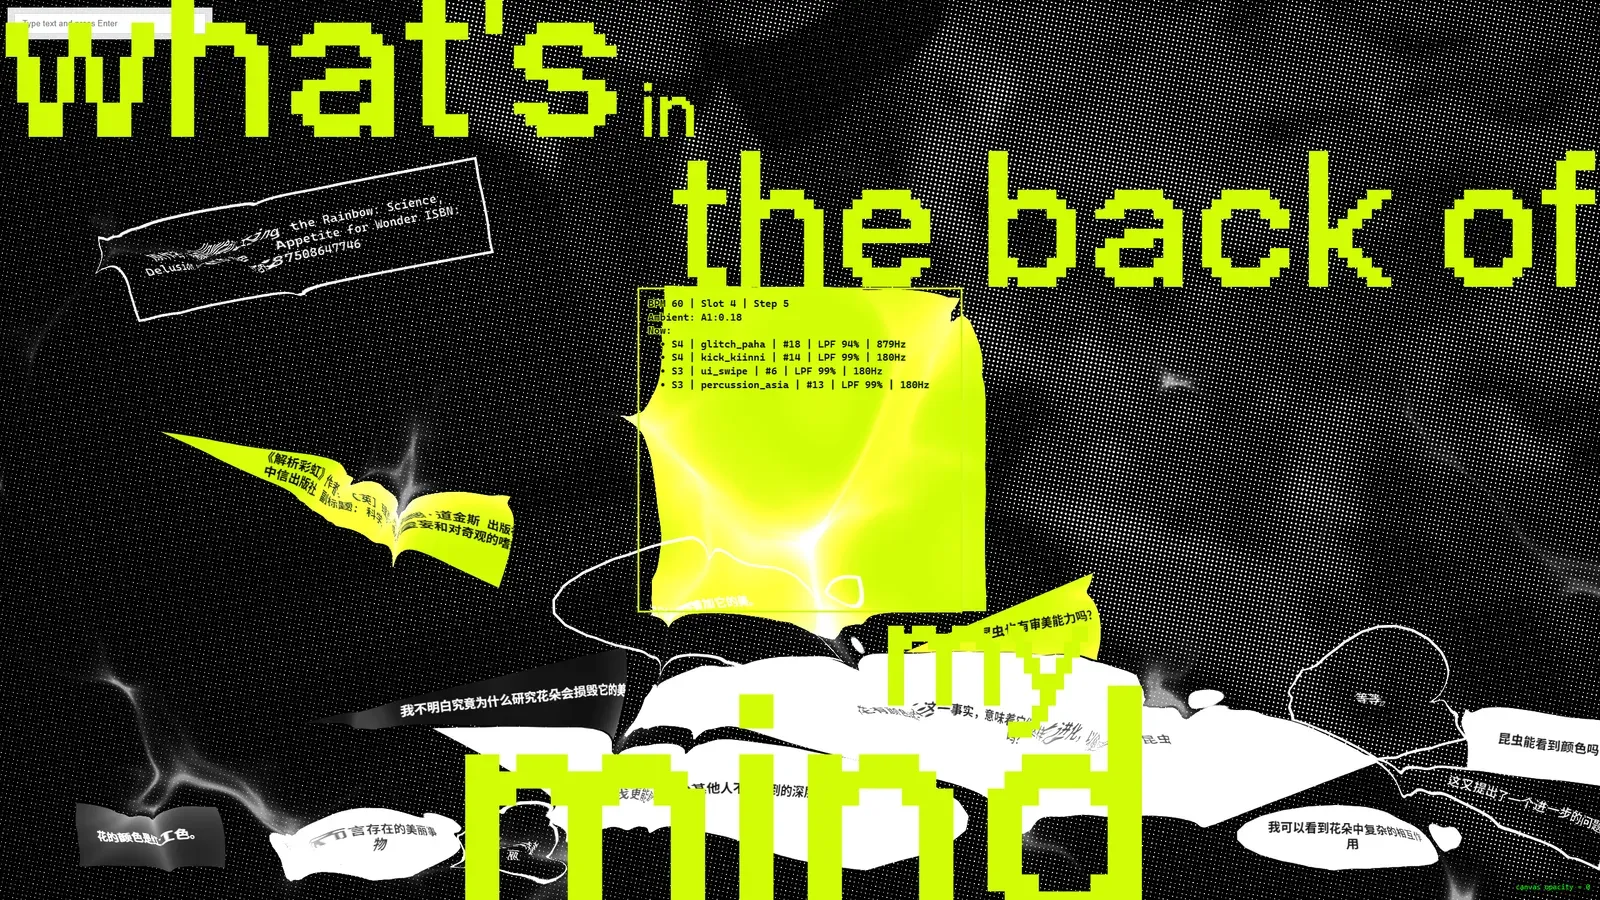
Sound Design
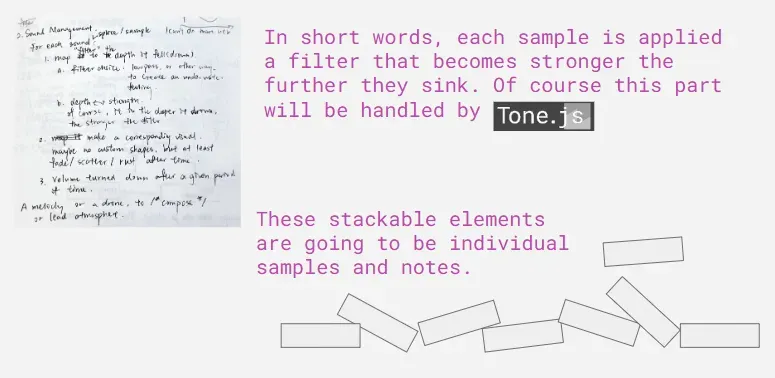
This time, I focused on: glitch, radio, ambient, and drone. Initially, I wanted to find vocal samples, since a lot of my inspirations use chopped voice fragments. But everything on Splice was either women scream or deep voiced men whispering seductively. What I needed was something fragmented, broken, or words that are barely comprehensible. So I decided to make the whispering a seperate part & real time generated. As for the samples & layers,
Samples
- Four longer ambient sounds for texture.
- Several sub-one-second samples that can be used as percussive elements.
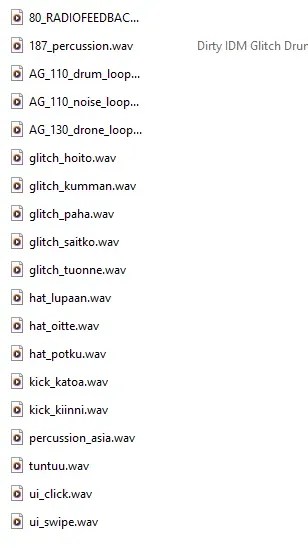
I also found an amazing sample pack & highly recommend it to everyone!! (If I ever seriously get into making music, this is the pack I’d definitely use.)
Whisper (Eleven Labs AI)
When I was exploring Eleven Labs’ AI voices, I initially just wanted to pick a nice “ASMR” voice.
But there were so many options.
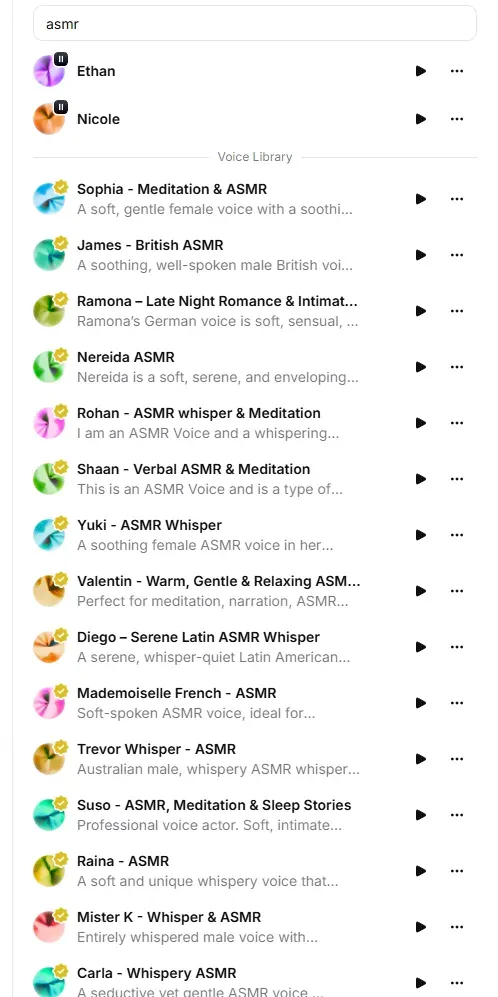
Then, a sudden idea hit me: What if I let a bunch of voices talk at the same time? That would sound so dreamlike.
So… I decided to do exactly that.
And then came the long coding session. I only meant to stream a basic text-to-speech, but after adding delay and randomness, I ended up writing way more code than expected. The most annoying part was that Eleven Labs only allows three voices per user, or it throws a 400 error. So stingy! So I gave in and paid for it. But honestly, the result turned out amazing.
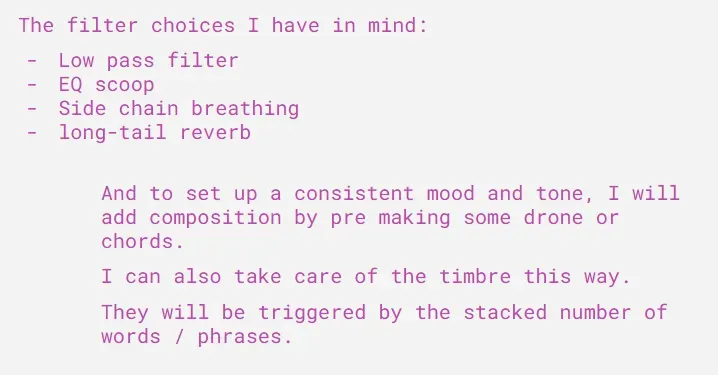
Filters
lowpass is mapped to depth for each individual sample.
Interaction Design
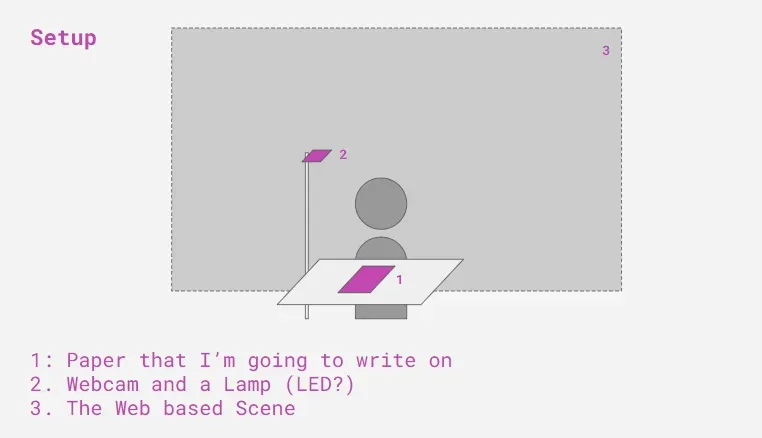
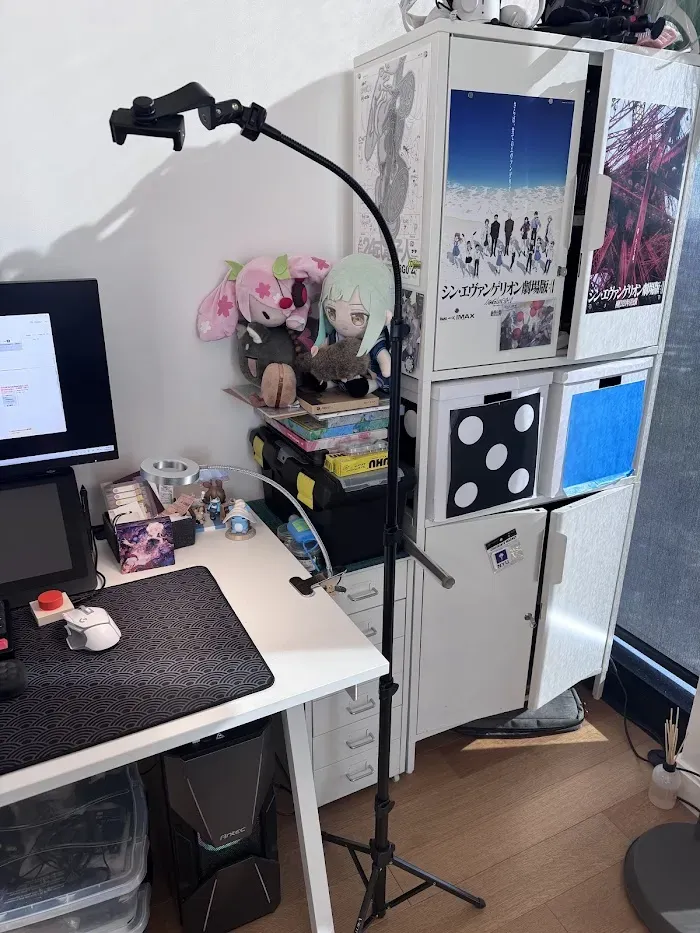
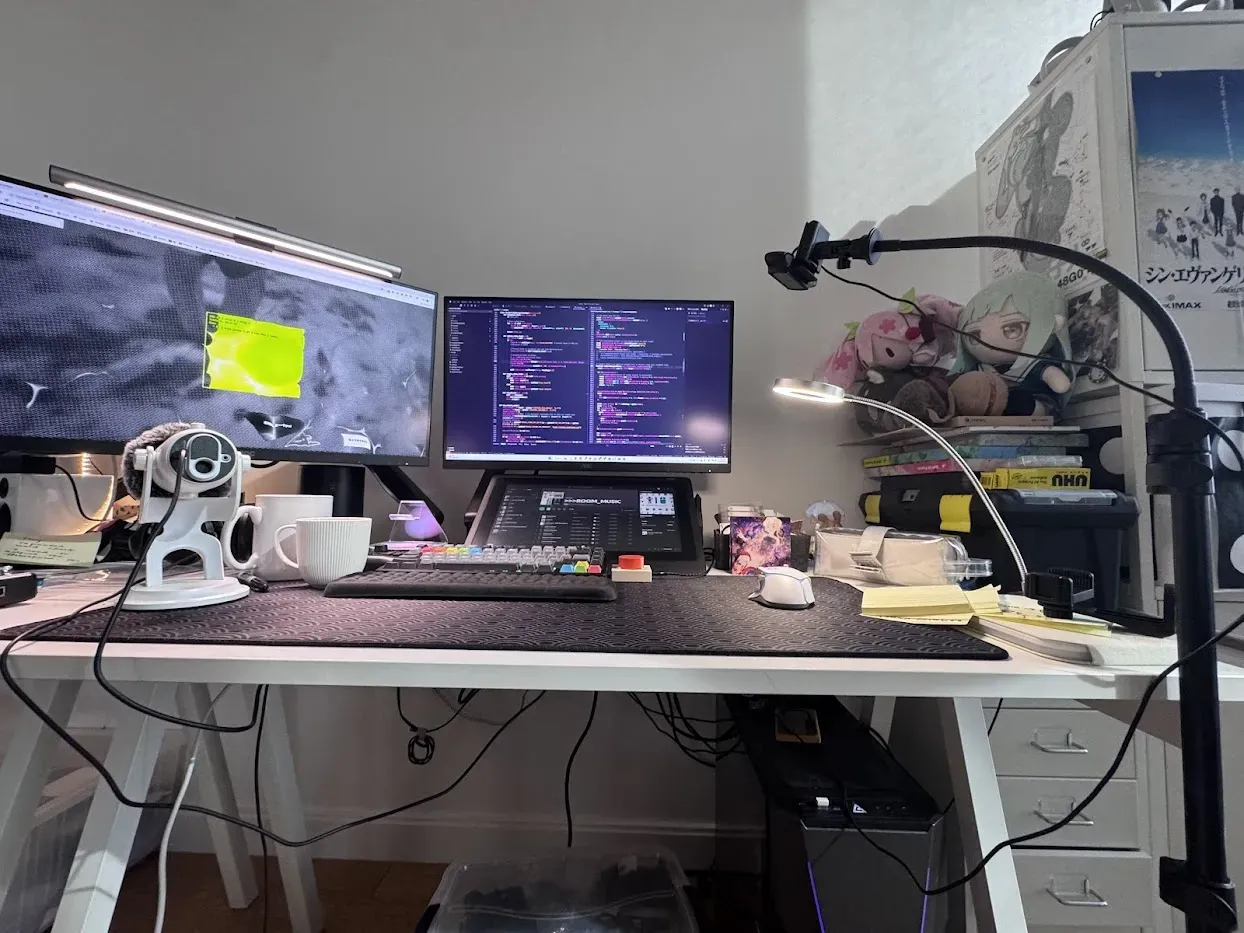
Set Up
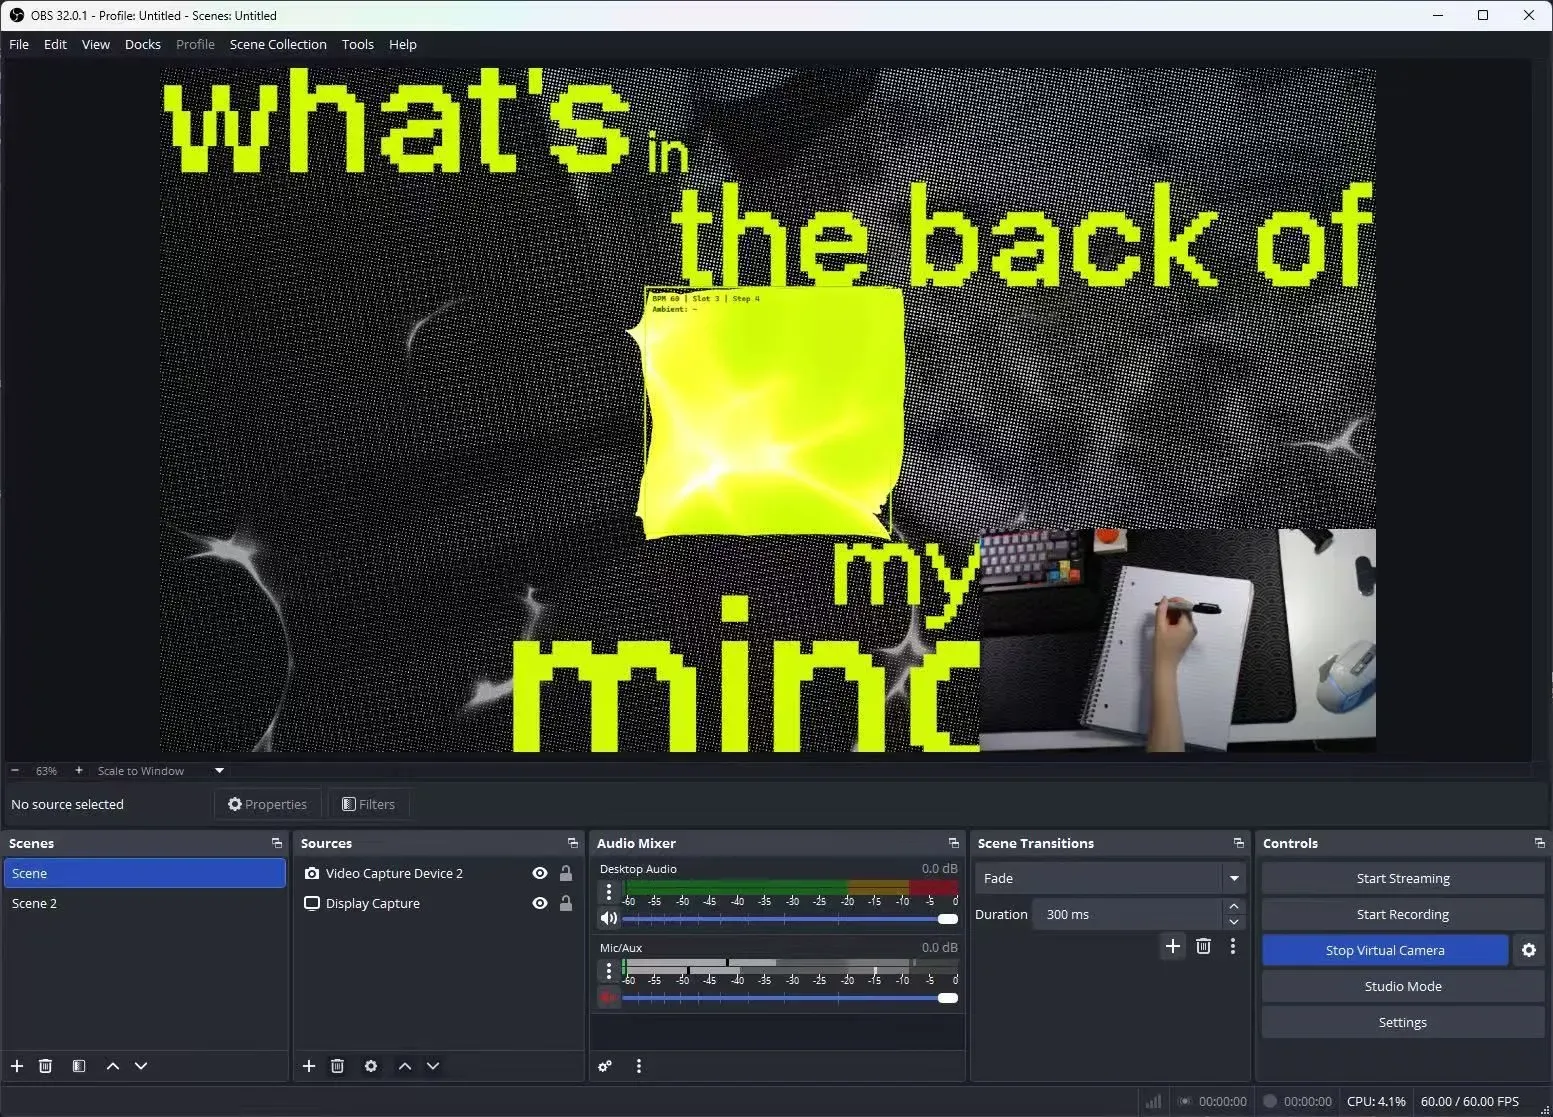
OCR Model
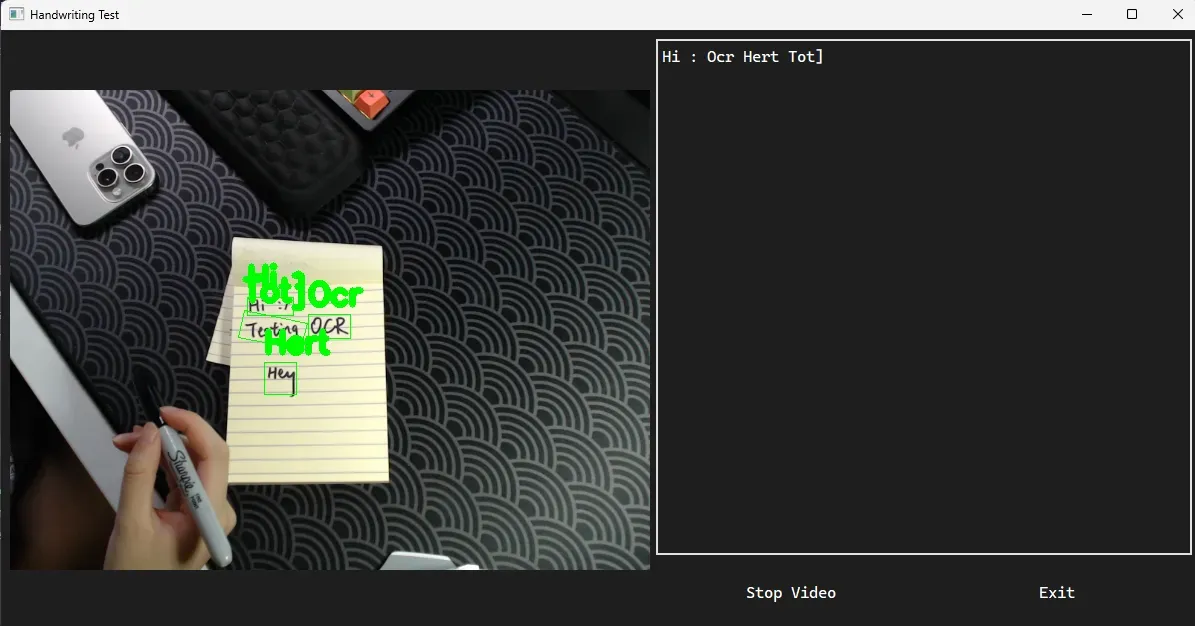
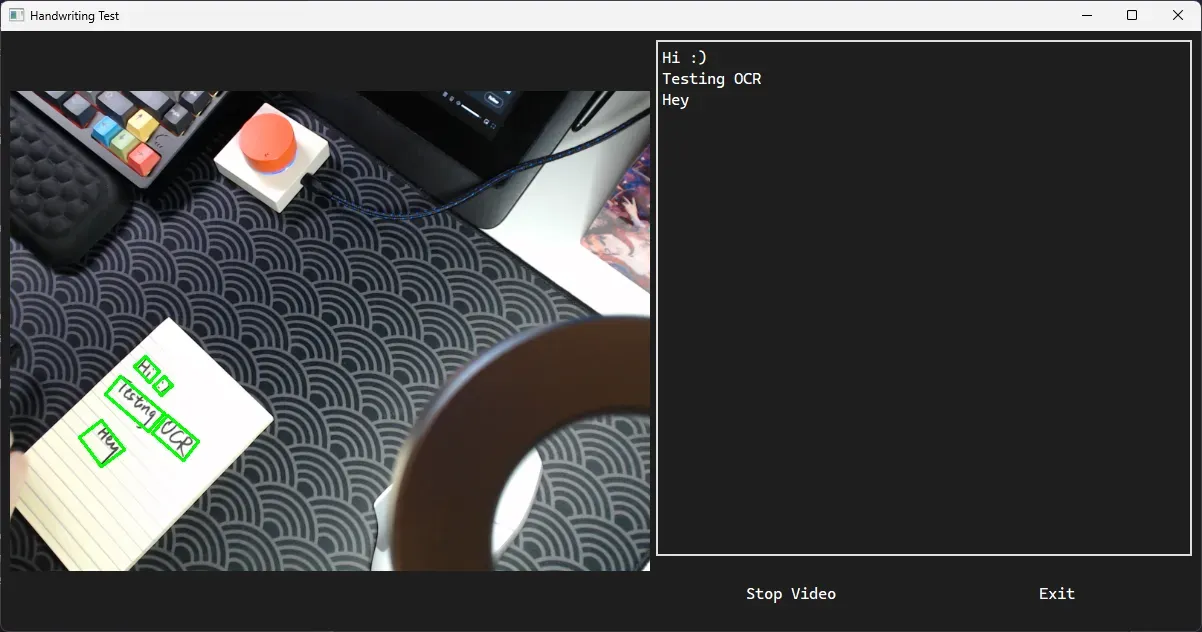
At first, I used EasyOCR, but it was incredibly inaccurate (as shown above).
So I started looking into paid models. Based on a few Reddit threads, I ended up choosing Google Cloud Vision API.
The documentation was painful to read, but it’s genuinely good. See for yourself:
It’s just expensive. Painfully expensive.
Incremental Recognition
Incremental recognition — this was by far the most frustrating part.
I spent two full weeks thinking about how to handle it, and honestly, I was scared to even start. I’ll keep it short here, since it’s really just me obsessing over a tiny, meaningless technical challenge.
At first, I thought it was purely an algorithm problem.
Later I realized it was actually a system design problem.
Trying to find an elegant solution easily traps you in a spiral—every approach feels wrong.
My goals were:
- Recognize only newly written parts (instead of reprocessing the whole page each time).
- Save bounding boxes for each recognized word, so later scans could skip those regions (I eventually abandoned this, but the artifacts still linger in my code).
- Avoid misreading hands or shadows as new strokes—basically improve robustness.
I went through tons of failed ideas:
- Frame differencing, comparing adjacent frames to detect new ink;
- Hand masking / background modeling, tracking hands so input only happens once;
- Bounding box caching, skipping already-covered regions by coordinates—my favorite in theory, but way too complex to implement.
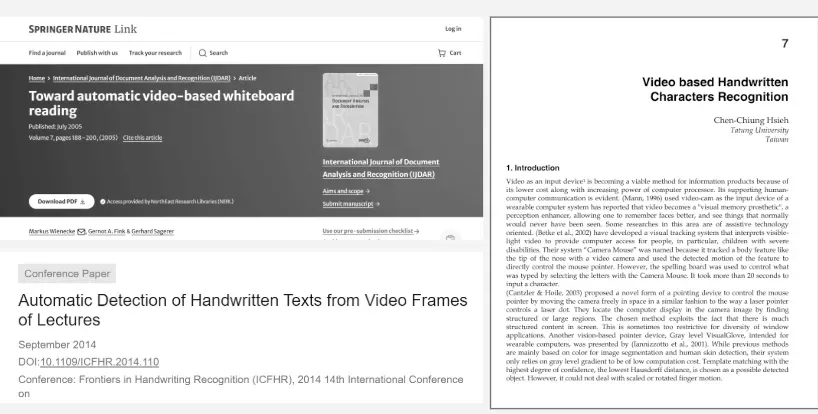
Honestly, if I cared enough, I could probably convince a CV-major friend to write a paper about it—because none of the high-citation papers I found actually solved this problem.
The best one was a whiteboard-text-detection project mentioning “handwritten,” “incremental,” and “OCR,” but even that didn’t have a full implementation: Automatic Detection of Handwritten Texts from Video Frames of Lectures | Request PDF
In the end, I gave up and went for the brute-force approach:
recognize everything captured by the webcam, regardless of whether it’s new.
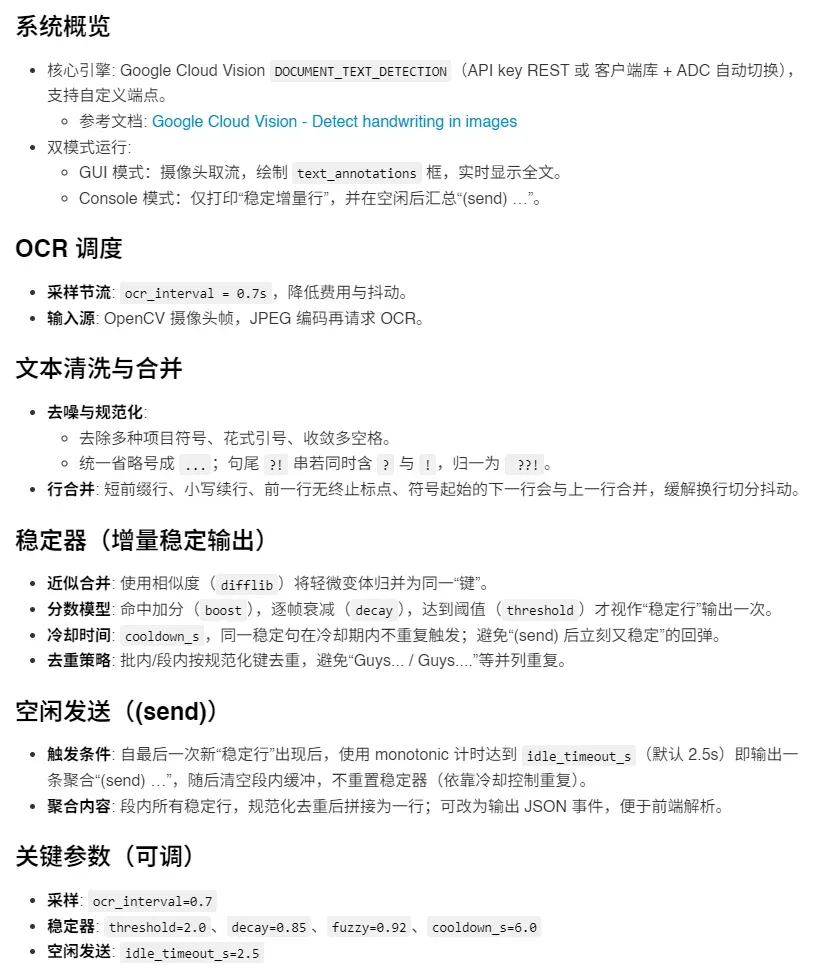
Then I stabilize the results on the backend—only printing a word when the same candidate appears consistently across multiple frames. Added a paragraph signature for safety.
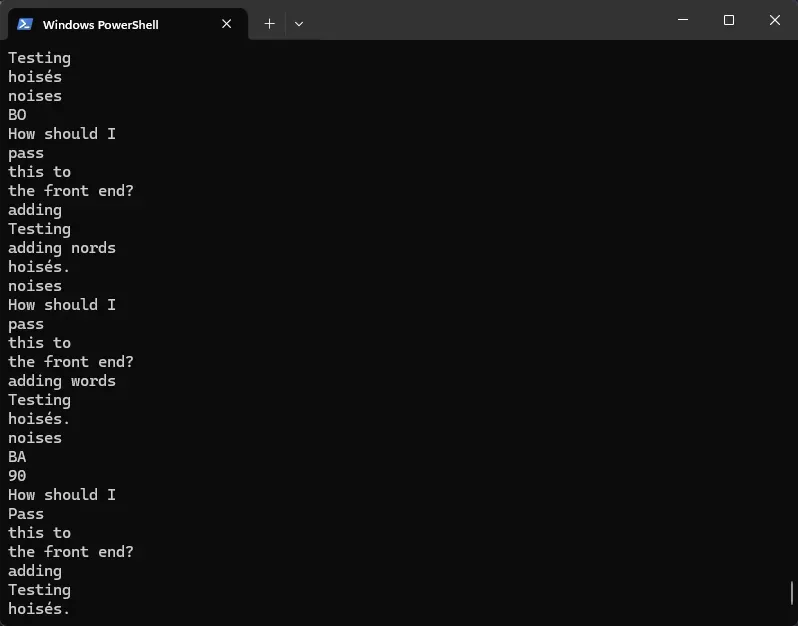
After noise reduction:
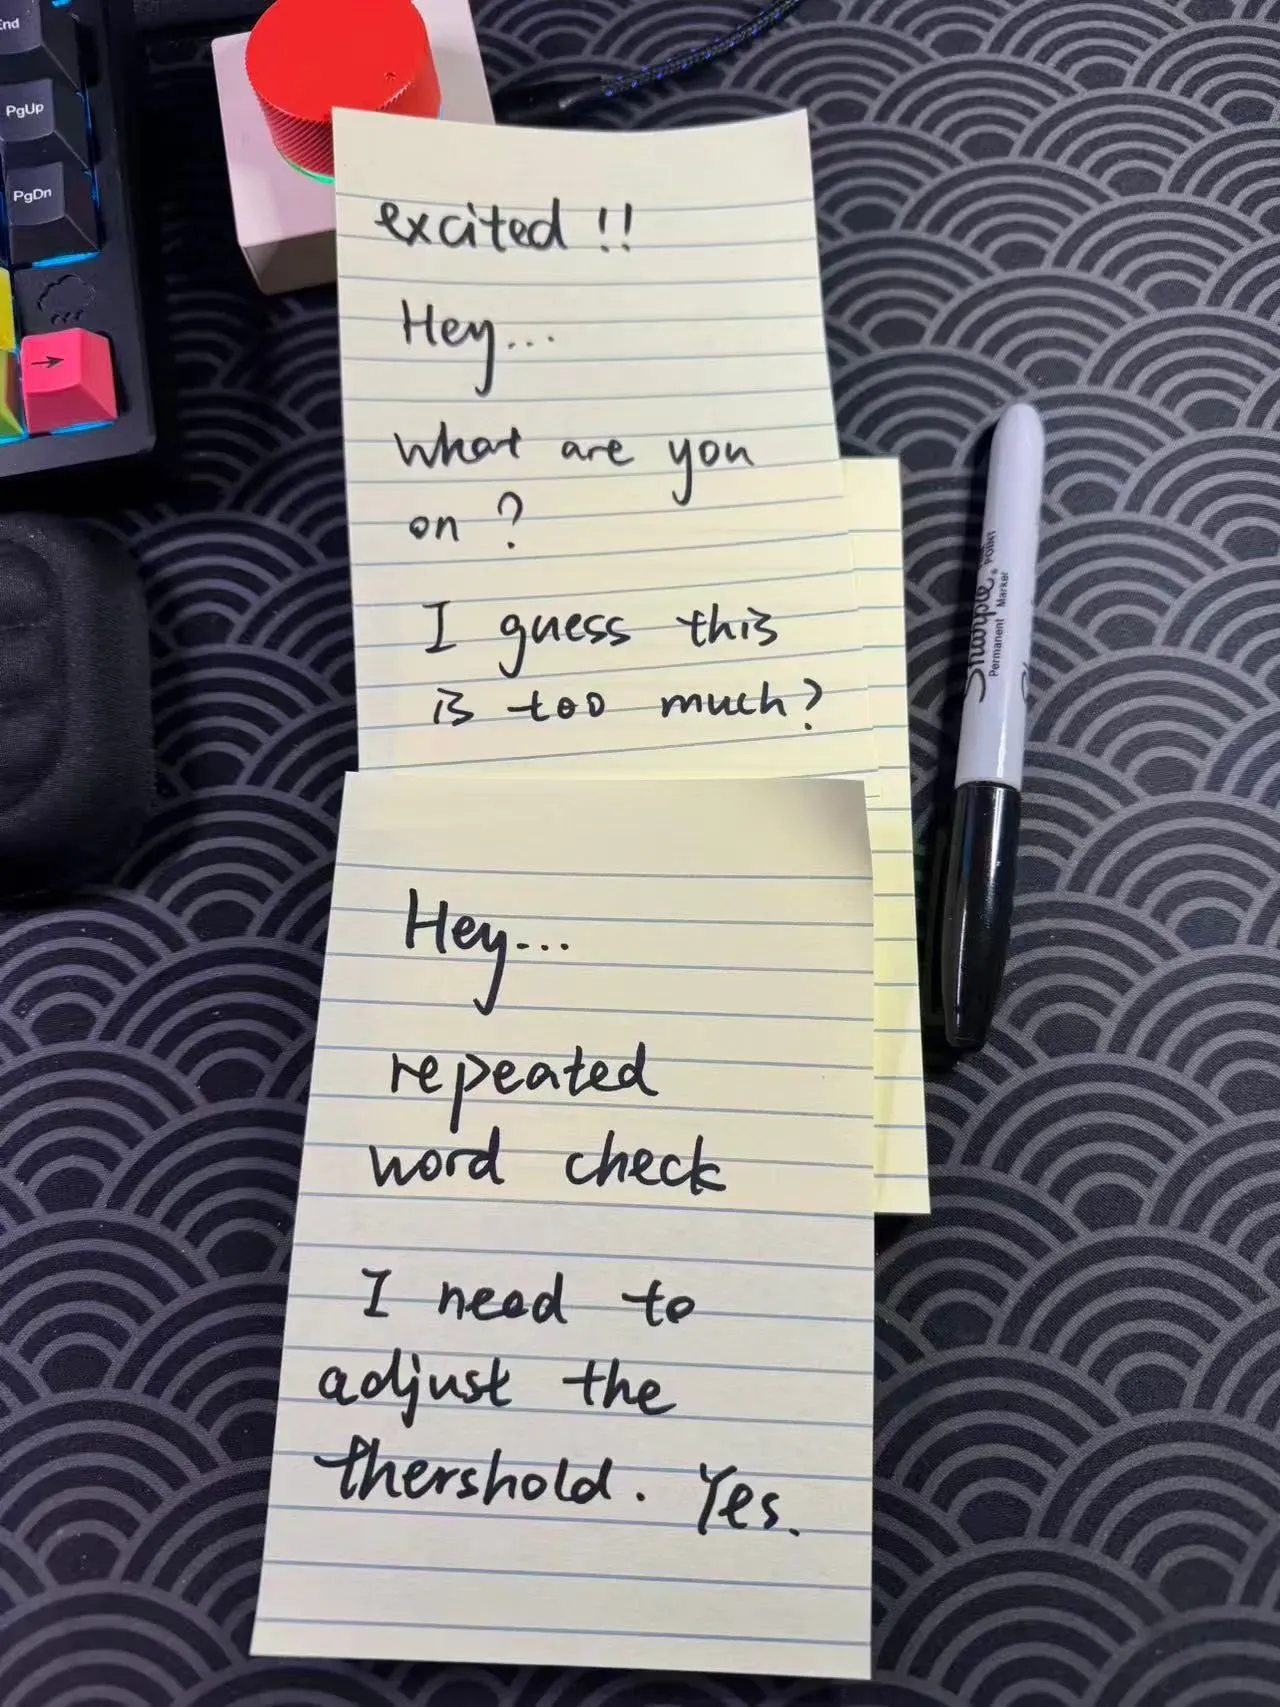
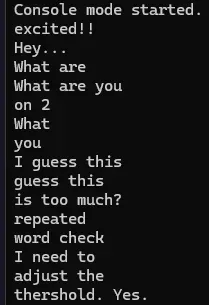
To make chunk timing work, I debugged until 2 a.m.
I was so done, but it finally worked.
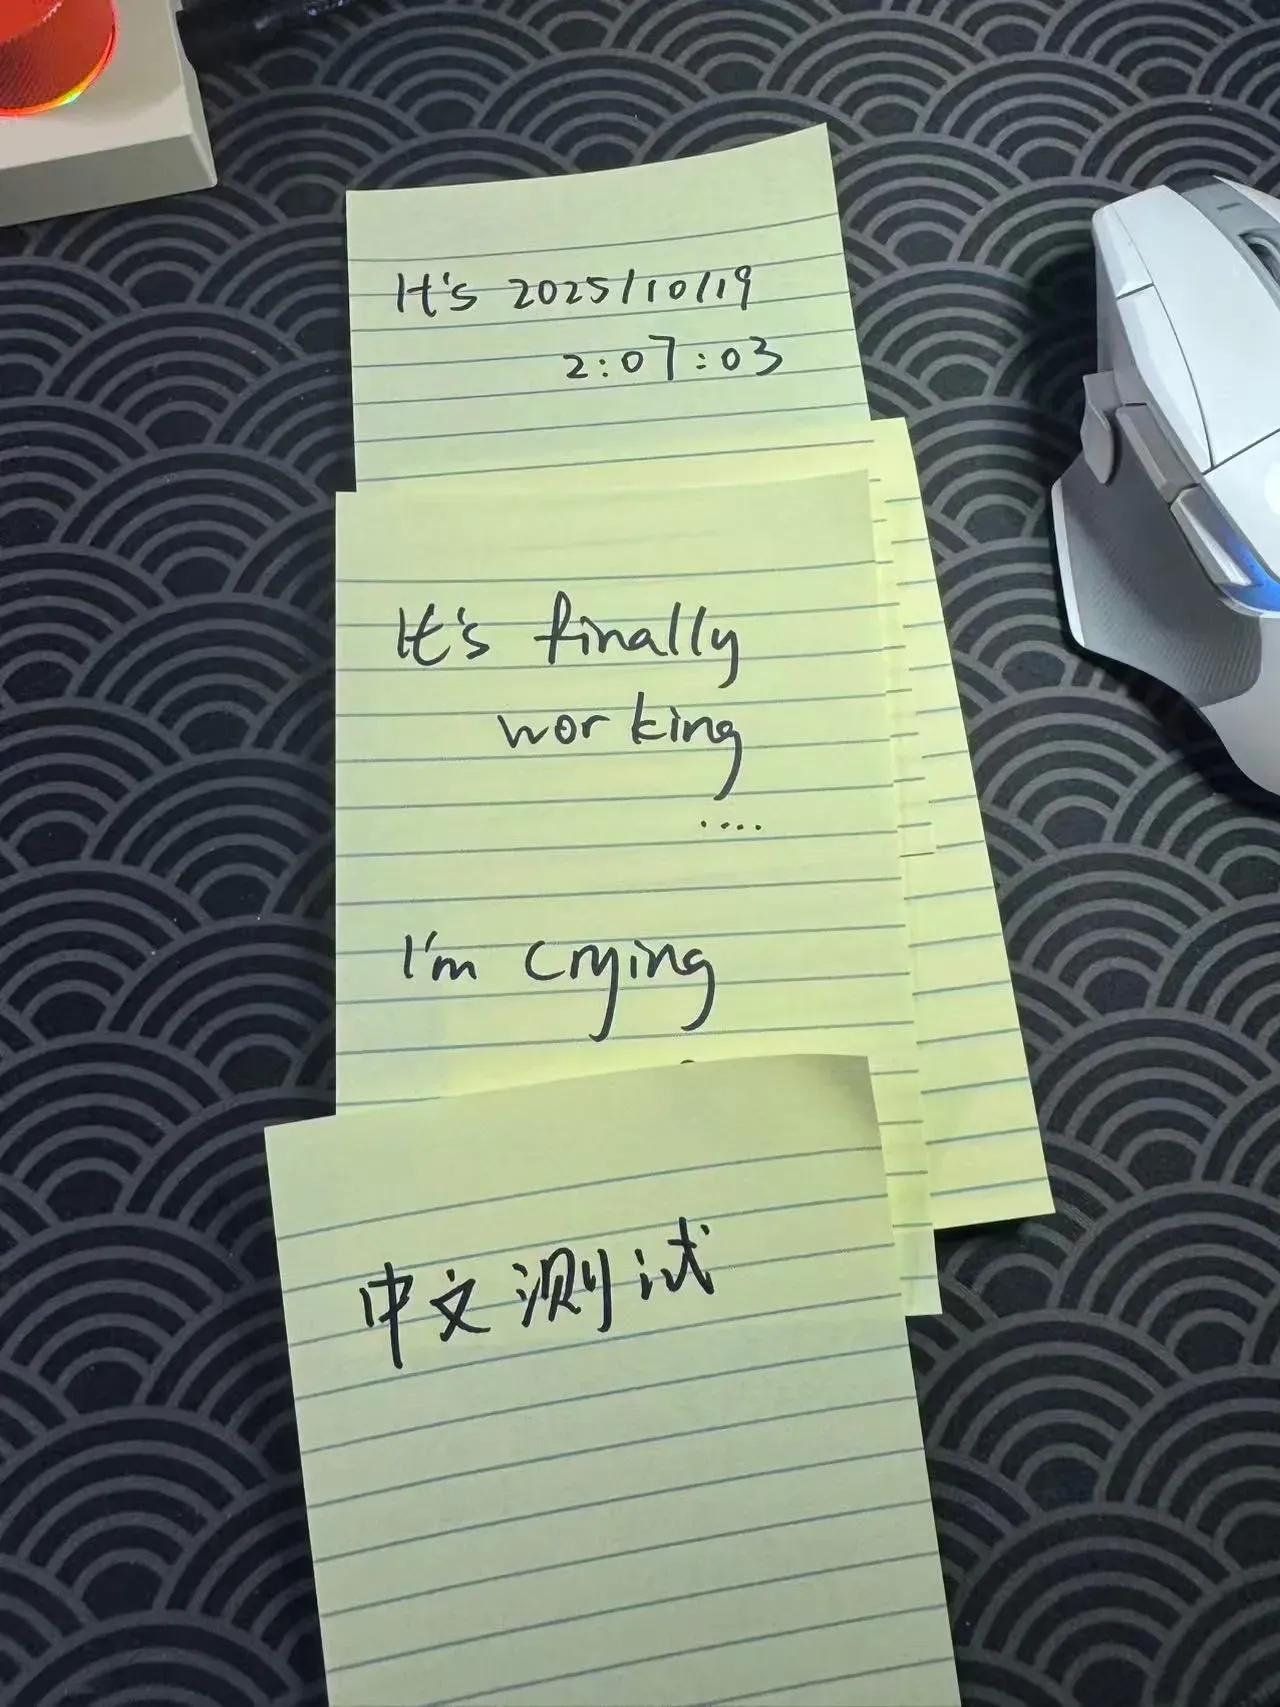
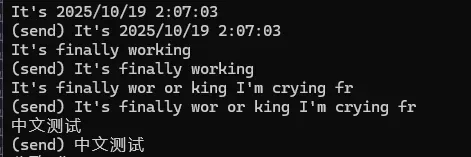
GPT later summarized how my final working version actually functioned: (in chinese)
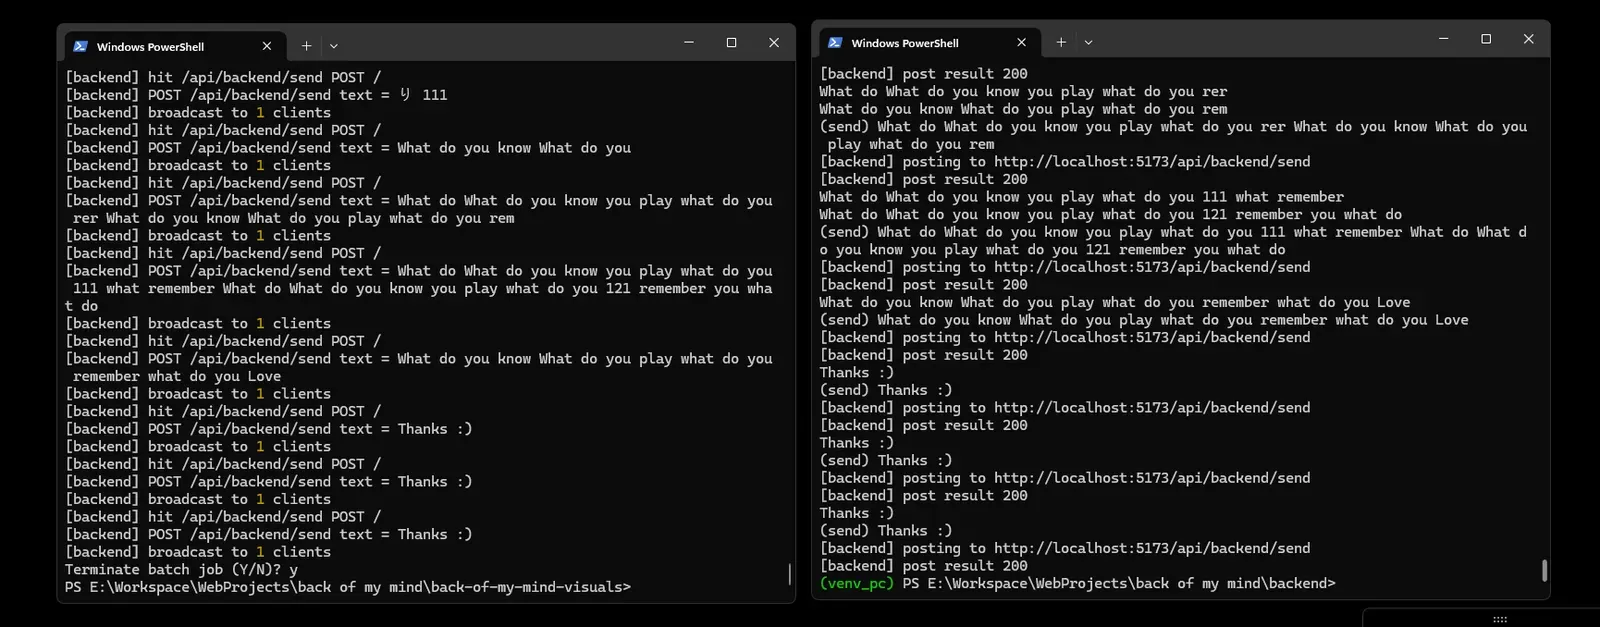
Frontend & Backend
Using port 5173 (Vite’s default)
Two terminals open for debugging and logging.
Writing Experience
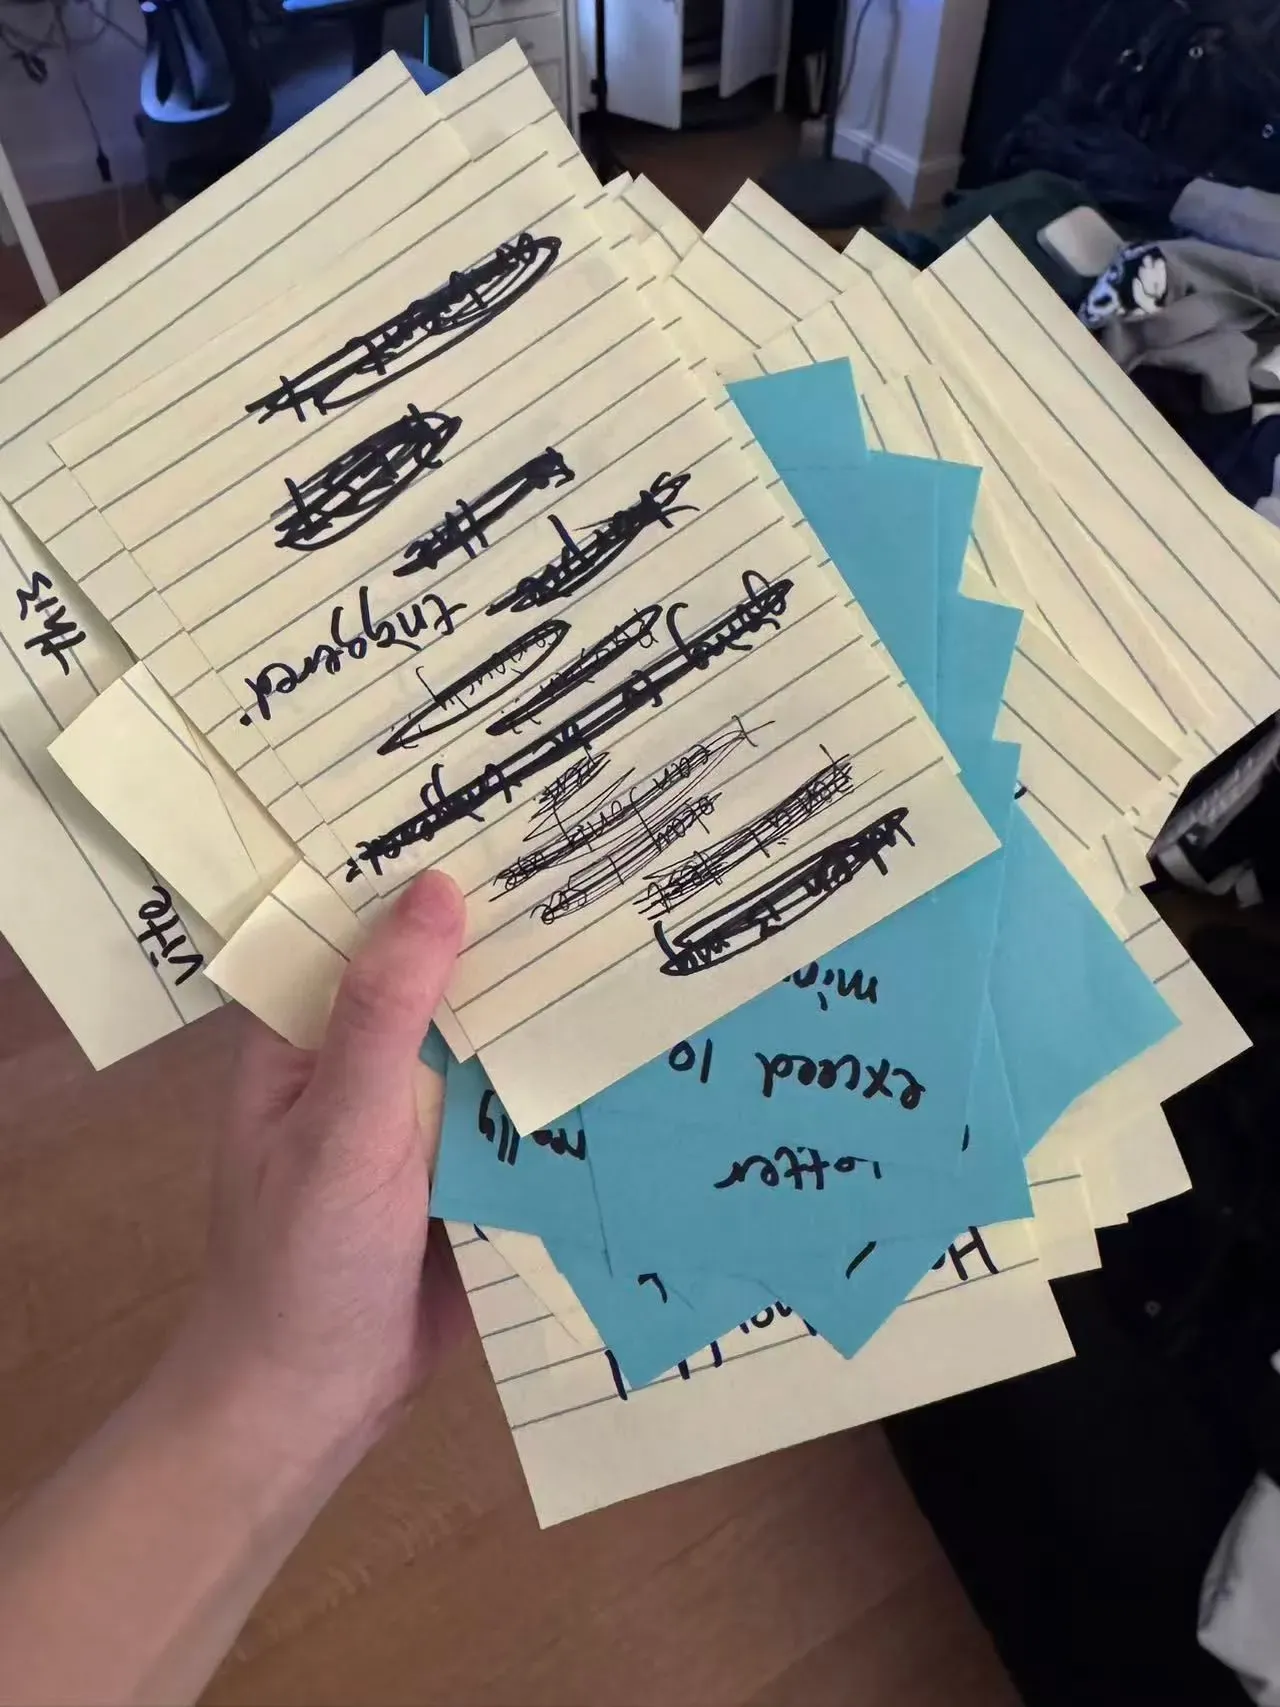
Finalized to use sticky notes.
Pointless Detour
Played around with Strudel for a bit.
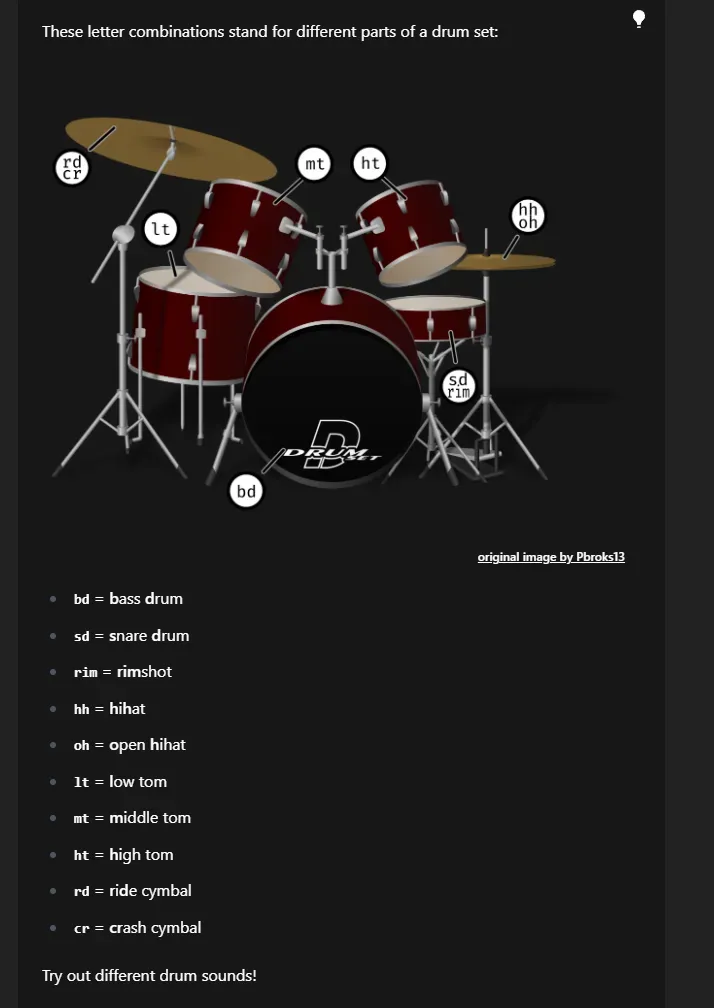
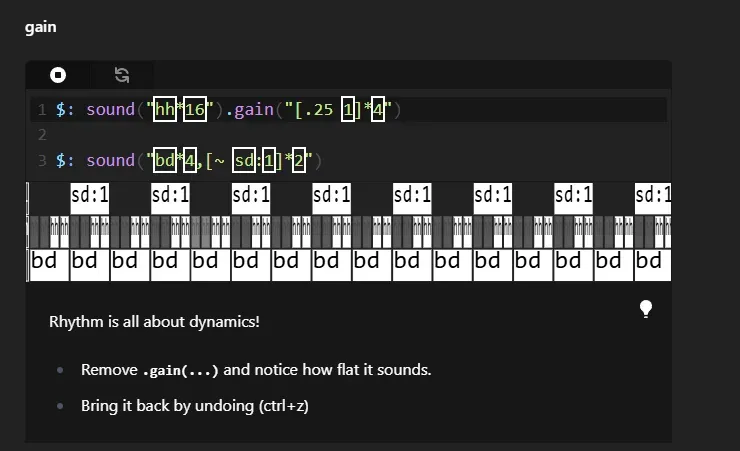
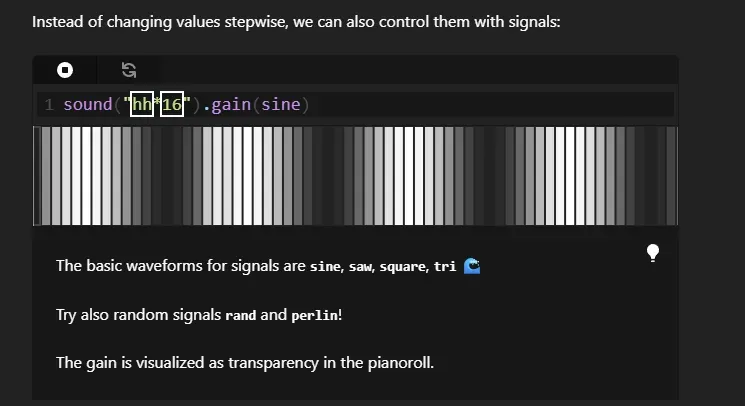
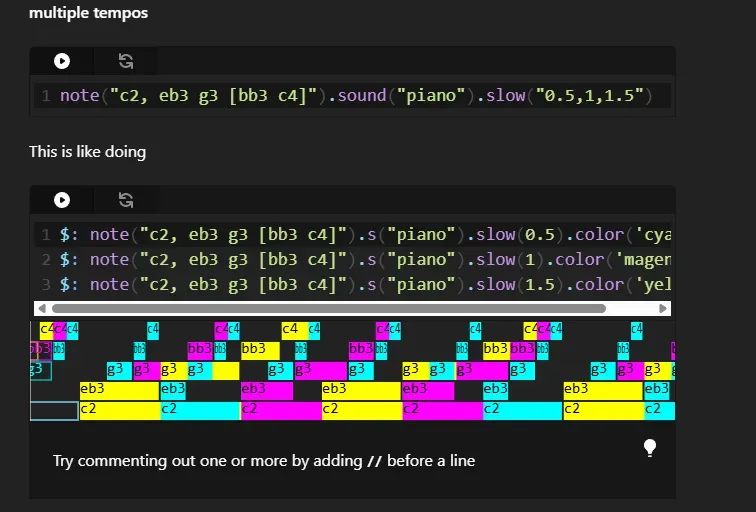
It’s a JS-based live-coding music environment inspired by TidalCycles—super fun to use.
Unfortunately, I couldn’t integrate it into my project.
So I went back to Tone.js in the end.